Big Data: ETL, Warehouses and Streaming
Build reliable analytical pipelines with batch/stream processing, lake and warehouse layers, and explicit freshness contracts.
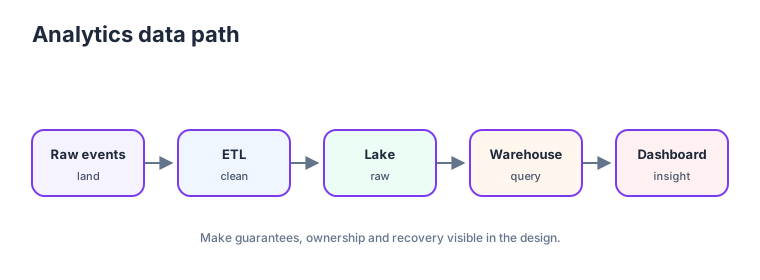 Analytics pipeline: raw events land durably, ETL/stream processing creates curated lake and warehouse datasets
MapReduce partitions large batch work into map, shuffle and reduce stages. ETL extracts, transforms and loads curated data. A data lake holds raw/flexible data; a warehouse optimizes governed analytical queries; a lakehouse combines lake storage with warehouse-style tables.
Lambda architecture combines batch truth with a speed layer; Kappa treats an ordered event stream as the main source and reprocesses it when logic changes. Choose based on team operations and freshness needs, not fashion. Record lineage, schema evolution, data quality checks and the age of the newest successful dataset.