Batch vs Stream and Data Modeling
Choose when work runs and shape data for correctness first, then deliberately denormalize proven read bottlenecks.
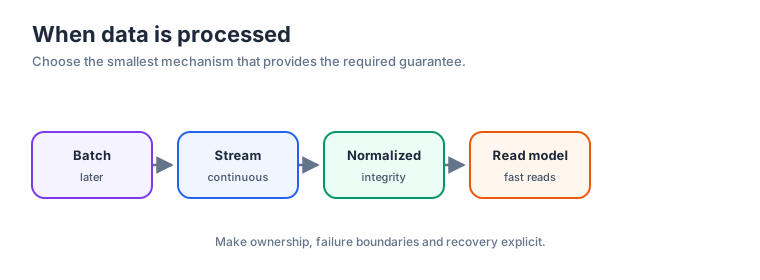 Batch runs a bounded set later; streaming handles events continuously while data modeling controls read and write cost
| Choice | Use when | Cost |
|---|---|---|
| Batch | Reports, backfills, daily billing | Results arrive later |
| Stream | Fraud alerts, live dashboards | Ordering/replay/deduplication |
| Normalized tables | Integrity and flexible writes | Reads may join |
| Denormalized read model | Measured read path is costly | Duplicates must stay in sync |
Streams need an ordering key, idempotency, retention and DLQ. Batch jobs need isolation so reporting cannot starve checkout. A denormalized projection needs an owner and a measurable freshness delay.